

Google AI Mode repeated 41.2% of the same business names when Cheers asked the same home-services question for the same city a week later; ChatGPT repeated 57.7%. Those are historical results from the Cheers Market Baseline, August 31 to September 20, 2026. A regional team that rewrites a location page after one missing answer risks spending its week fixing ordinary variation.
Last verified: October 31, 2026.
Keep the question, city and engine fixed, then inspect the next answer before assigning work. Correct a verified wrong phone number or service claim immediately; a missing name needs more context.
How much the local list changed
Our September analysis covered 34,742 usable answers to 32 home-services questions in 100 US and Canadian metro areas. For each question, city and engine, we compared the names in one week's answer with the names in the next. Gemini repeated 42.6%, between Google AI Mode and ChatGPT.
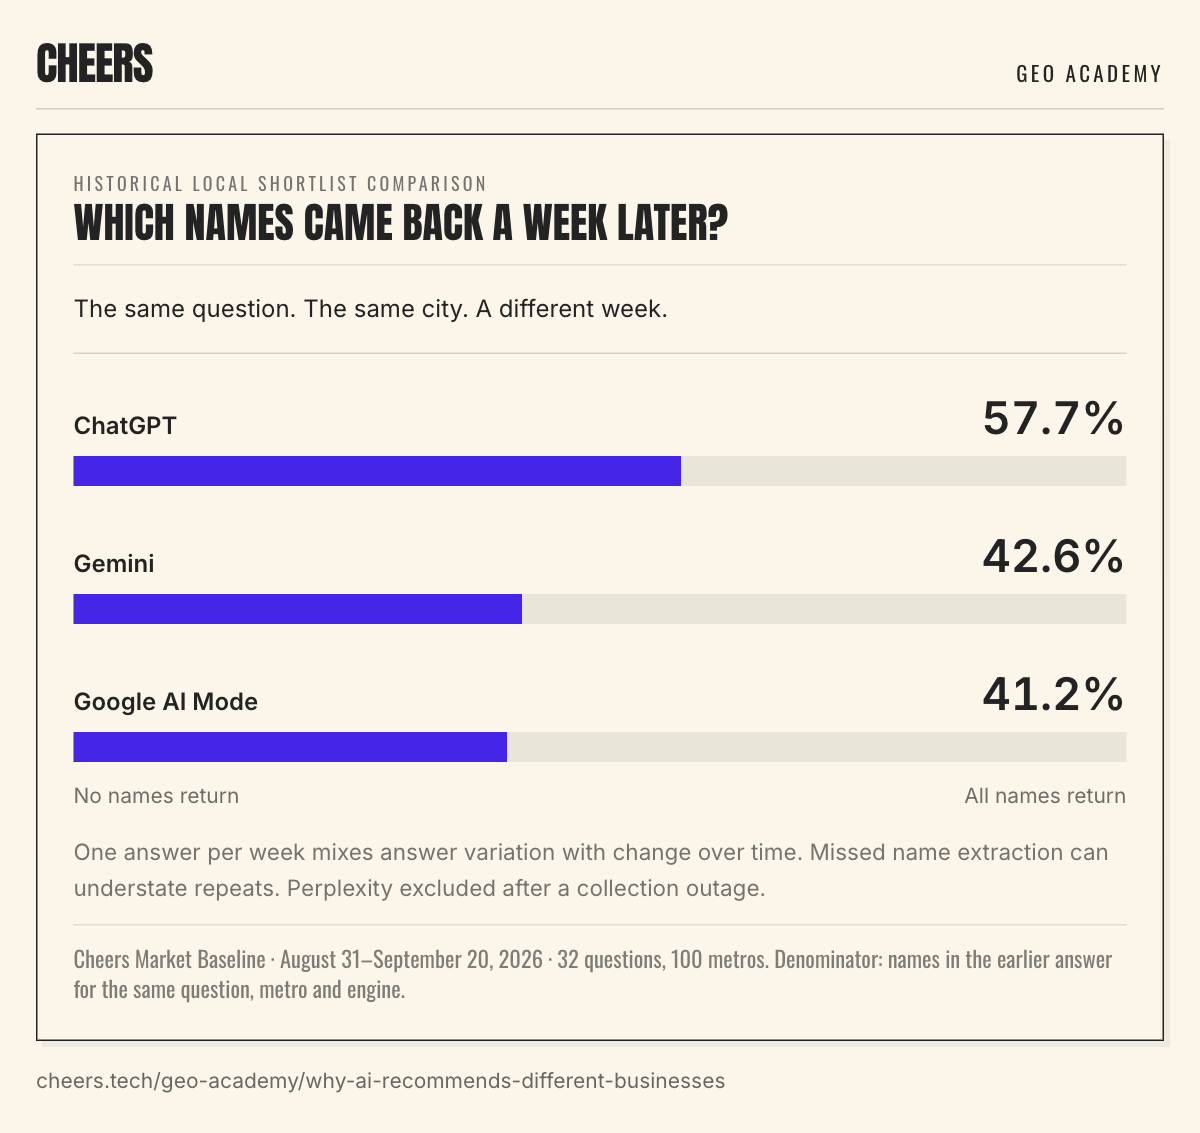
The whole list repeated less often than an individual name. Only 7.2% of ChatGPT week pairs had identical lists; Google AI Mode's figure was 2.4%. In 19% of Google AI Mode pairs, none of the previous names returned. That happened in 5% of ChatGPT pairs and 21% of Gemini pairs.
Why the names can change
Google says AI Mode and AI Overviews can search related subtopics and sources while preparing an answer. Different models and techniques can produce different responses and links. That makes changing retrieved sources one plausible explanation for changing recommendations.
Our weekly comparison cannot tell you which cause did the work. We asked once per question, city and engine each week, so ordinary answer variation is mixed with changes in sources, models and the businesses themselves. Automatic name extraction also missed some businesses, pushing measured repeat shares down. Perplexity is excluded from repeat calculations because a collection outage left too few weekly pairs.
The useful question is narrower than "Did AI change its mind?" Check whether your branch disappeared, whether the competing names changed and whether the answer contains a wrong fact. Those events deserve different responses.
When a change deserves action
A different prompt or city is a different test. Compare the conditions before interpreting movement. If they match and a branch keeps disappearing, open the sources behind the competing recommendations and inspect the missing branch's public information.
A branch disappeared from an answer
Check the fact, then the pattern
Wrong business fact?
Yes →Correct the source
Wrong phone, closed branch or unavailable service.
Otherwise, check conditions ↓
Same test conditions?
No →Repair the comparison
Match question, city, engine and search behavior.
If conditions match, check the pattern ↓
Repeated absence?
Yes →Inspect cited sources
Compare competitor evidence with your branch.
One missing name, with no confirmed error? Save the answer and check again.
Cheers editorial workflow · October 31, 2026. Informed by the historical local study and Google AI features guidance.
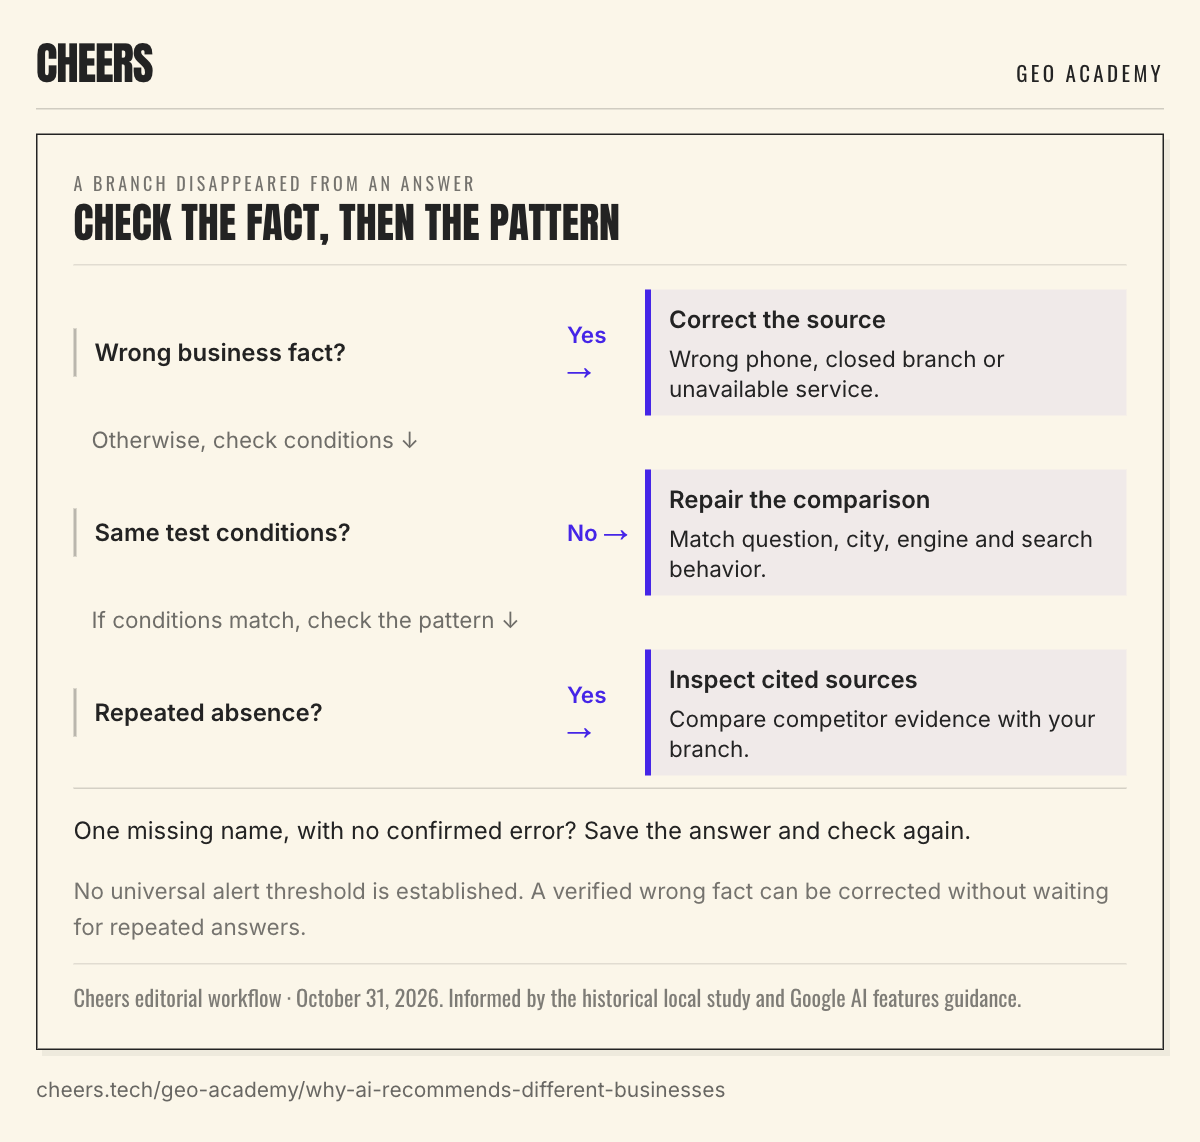
A closed branch listed as open, a wrong number or a service the branch cannot provide needs a source correction as soon as you verify it. You do not need weeks of measurement to establish that the information is wrong.
The original review analysis offers context, not a repair formula. Among businesses Google AI Mode named at least once, those showing 1,000 or more reviews returned in at least two of three weeks 43.3% of the time, compared with 25.7% for fewer than 20 reviews. Review count also tracks age and size; that association cannot tell you how many reviews would cause a missing branch to return. See the review-count guide before turning it into a target.
For persistent misses, use the competitor recommendation guide to assign a specific page, listing or source investigation.
A changed shortlist can still include your branch
The following fictional example illustrates the calculation. The first list names Cedar, Harbor, Pine and Summit. The second names Cedar, Harbor, Maple and Valley. Two of the four earlier names returned, so shortlist repeat share is 50%. Cedar still appeared in both checks: its branch mention rate in this tiny example is two out of two.
Fictional example · no engine capture
The list changed. Cedar stayed.
Earlier answer
Later answer
2 of 4 = 50%
Earlier names returned
2 of 2
Answers named Cedar
Cheers measurement illustration · October 31, 2026. Invented business labels and lists explain denominators; no observed engine result or customer data.
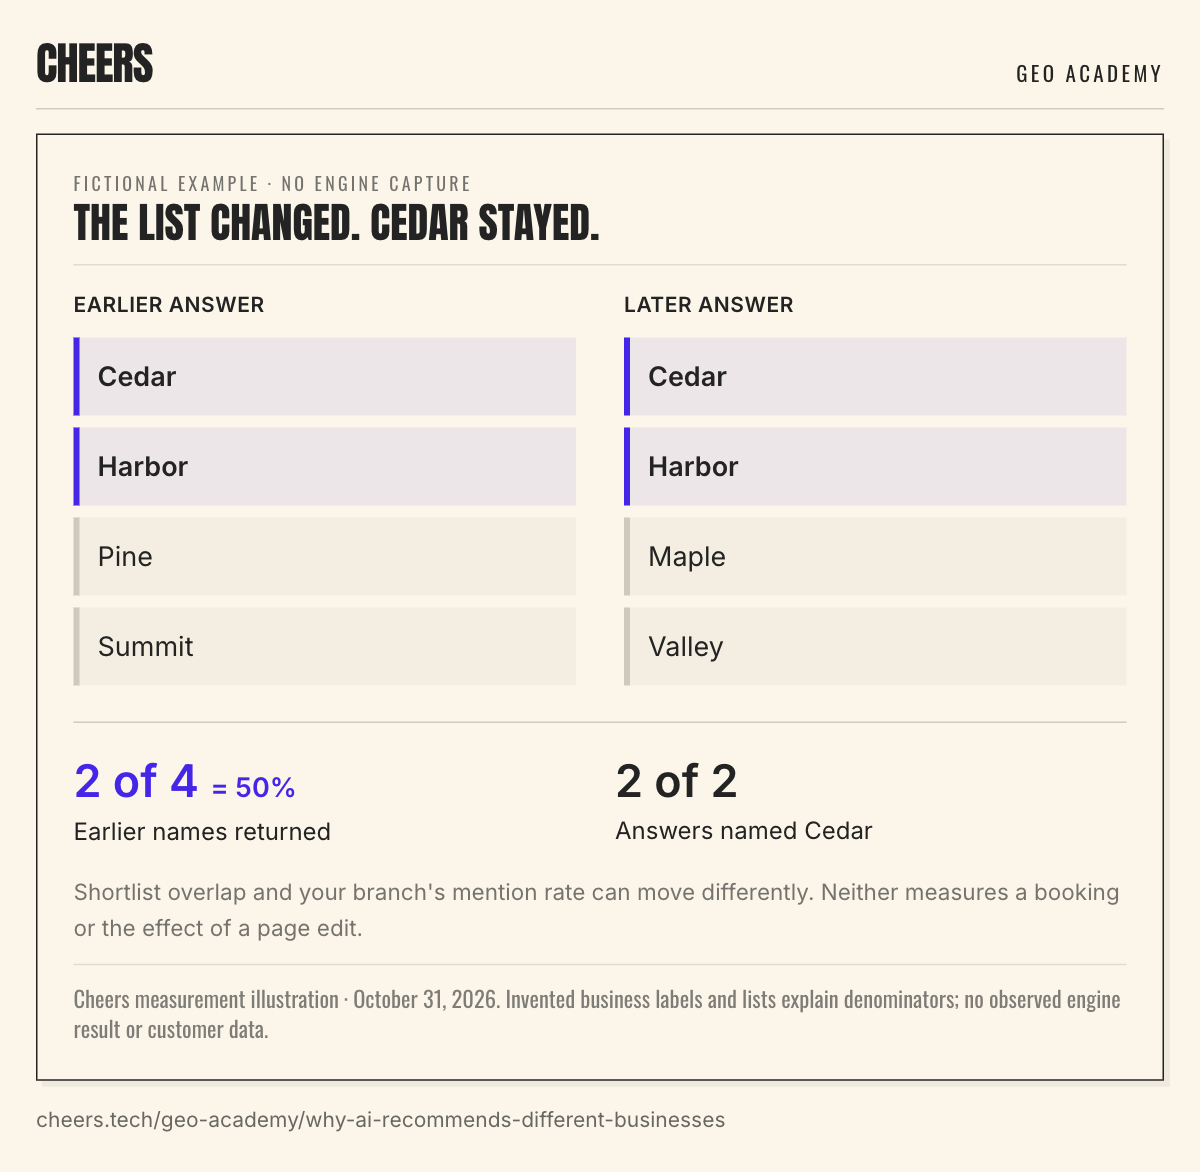
These are different denominators. Repeat share starts with names in the earlier list. Branch mention rate starts with answers in the chosen sample. Neither number says whether a customer called or whether a page edit caused the result. In a real portfolio report, identify the specific branch; a parent-brand mention can conceal a missing treatment location or service area.
The AI visibility score guide explains how to keep those underlying observations visible instead of blending them into an unexplained score.
The pool is bigger than one answer
In the original Cheers analysis, Google AI Mode and ChatGPT each named a median of eight different businesses for the same question and city over three weekly checks. Only 12% of Google AI Mode's business-question-city combinations appeared in all three weeks; ChatGPT's share was 25%. These are lower-bound counts because extraction can miss names.
The engines also kept different shortlists. Across 5,347 occasions when all four engines answered the same question for the same city and week, 76.5% of the named businesses appeared in only one engine, 16.2% in two, 5.8% in three and 1.6% in all four. Only 17% of those occasions included any business all four named. Missed extractions can understate agreement here too.
That is why a national yes-or-no screenshot is a weak way to prioritize branches. Keep the report by location, buyer question and engine. Preserve the named businesses and source links so a manager can examine the missing branch rather than argue about the brand average.
Record whether the answer searched
The Gemini API documentation says an enabled search tool lets the model decide whether search would help. Keep executed search steps and grounding or citation records with the requested and returned model version. When execution evidence is missing, mark search use unknown.
Keep API tests, consumer-app checks and web-grounded local answers in separate series. A change in model, location context or search behavior needs a note in the report before you compare rates. The location and session guide covers those controls.
Set up a useful comparison this week
Choose priority branches and buyer questions before looking at results. Five locations, three questions, two engines and two checks would produce 60 answers. That is an illustrative workload, not a validated sample-size threshold. Save the answer, date, engine, location context, business names and source links together.
Review the exceptions with the regional manager. Fix incorrect business facts, investigate repeated absences and label comparisons whose conditions changed. The multi-location audit guide supplies the wider workflow; the AI Visibility Grader offers a one-business starting snapshot.
A separate finding about forecasting mentions
An October 14 preprint by Dmitrij Żatuchin repeated 162 requests about 12 software brands on gemini-3.1-pro-preview after 20.3 days. Its history-based forecast scored Brier 0.0281, a squared probability error where lower is better. That is not 97.19% accuracy.
No answer executed search, although search was enabled. The study covers one model and interval, estimates no decay rate and counts lexical mentions, including negative ones. The author discloses founding and holding equity in its funder, Rankfor.AI. This supports a bounded finding about software-brand mention persistence, not a forecast for a local hiring shortlist.
If a vendor forecasts your branch's visibility, ask it to define the outcome and freeze its predictions before the next checks. Compare them with a simple recent-history baseline on the same future observations. Prediction quality and the effect of a marketing change require separate tests.
Methodology and update note
The local findings retain the original August 31 to September 20, 2026 window. Cheers asked four engines the same 32 home-services questions across 60 US and 40 Canadian metro areas. The analysis used 34,742 usable answers: 9,434 ChatGPT, 9,435 Google AI Mode, 9,364 Gemini and 6,509 Perplexity. Empty and cut-off answers were excluded, mostly from a Perplexity collection outage.
Names were matched by normalized business name within each metro. ChatGPT and Gemini use answer-text names; Google AI Mode includes its place cards. One question was asked per city and engine each week, so the study does not separate ordinary sampling variation from change over time. A hand check of 40 answers found extraction caught about three in four names across engines and 92% on Google AI Mode. Counts and agreement can be understated. Perplexity is excluded from repeat and persistence calculations. Review bands use the highest count Google AI Mode displayed for a business in that metro; they describe association, not causation.
Reorganized October 31 to put the local findings and action decision first; added a fictional overlap example. This refresh adds no new Cheers data pull and does not extend the historical observation window. The operator examples and 60-answer pilot are editorial recommendations.
Sources
Checked October 31, 2026.
- Twenty Days Later. Żatuchin, submitted October 14, 2026. Full preprint, including methods and disclosures.
- AI features and your website. Google Search Central. Source for fan-out and response variation.
- Grounding with Google Search. Google AI for Developers. Source for tool execution and grounding evidence.
- Cheers research methodology. Previously published Market Baseline analysis, August 31 to September 20, 2026, aggregate only. Source for the local repeat, pool, overlap and review figures retained here.
Dylan Allen-Arnegård is the CEO & Co-Founder of Cheers, the done-for-you local visibility partner for established home-service companies and PE-backed portfolios.